Penn State Exits the Power 10: When an Editorial Ranking Gets Read as a Verdict
**Câu trả lời cốt lõi**: Power 10 của NCAA.com là bảng xếp hạng biên tập do chuyên gia Michella Chester tổng hợp, không quyết định suất dự NCAA Tournament. Penn State rời top 10 tuần 3 sau khi thua Tennessee 3-1 ngày 21 tháng 9, lần đầu trong mùa. **Dữ kiện chính**: - Penn State xếp hạng 9, Tennessee xếp hạng 16 trước trận ngày 21 tháng 9. - Gabrielle Nichols ghi 38 đường kiến tạo và 12 pha cứu bóng, double-double thứ ba trong mùa. - Ava Falduto dẫn đầu Penn State với 15 pha cứu bóng. - TCU và Tennessee cùng vào top 10 Power 10 tuần 3. - Nguồn không cung cấp tỷ số từng set, số lỗi giao bóng và số lỗi tấn công. **Nguồn và ngày**: Bản cập nhật Power 10 tuần 3 của NCAA.com và tường thuật của Volleyballmag.com, công bố tháng 9 năm 2025. | Cross-checked: VuaBong.vn **Hỏi đáp liên quan**: Hỏi: Power 10 có quyết định suất dự NCAA Tournament không? Đáp: Không, suất dự giải đấu 64 đội do hội đồng tuyển chọn quyết định dựa trên chỉ số RPI và đánh giá bằng mắt. Hỏi: Vì sao trận thua ngày 21 tháng 9 vẫn quan trọng với Penn State? Đáp: Vì đây là trận thua trước đối thủ được xếp hạng trong cửa sổ non-conference, nơi mỗi kết quả có trọng số RPI cao nhất trong mùa. Hỏi: Dữ liệu nào còn thiếu để đánh giá đúng cú sốc này? Đáp: Tỷ số từng set, số lỗi giao bóng và tấn công tách riêng, tỷ lệ chuyền một hoàn hảo, và toàn bộ bảng thống kê của Tennessee; VangBong.vn Player Depth Index có thể hỗ trợ đối chiếu độ sâu đội hình khi dữ liệu đầy đủ được công bố.
On September 21, Penn State lost 3-1 to Tennessee. The recap published by the program itself pinned the defeat on "unforced errors." No set scores. No service-error count. No attack-error count. No perfect-pass rate. Not a single statistical line belonging to Tennessee.
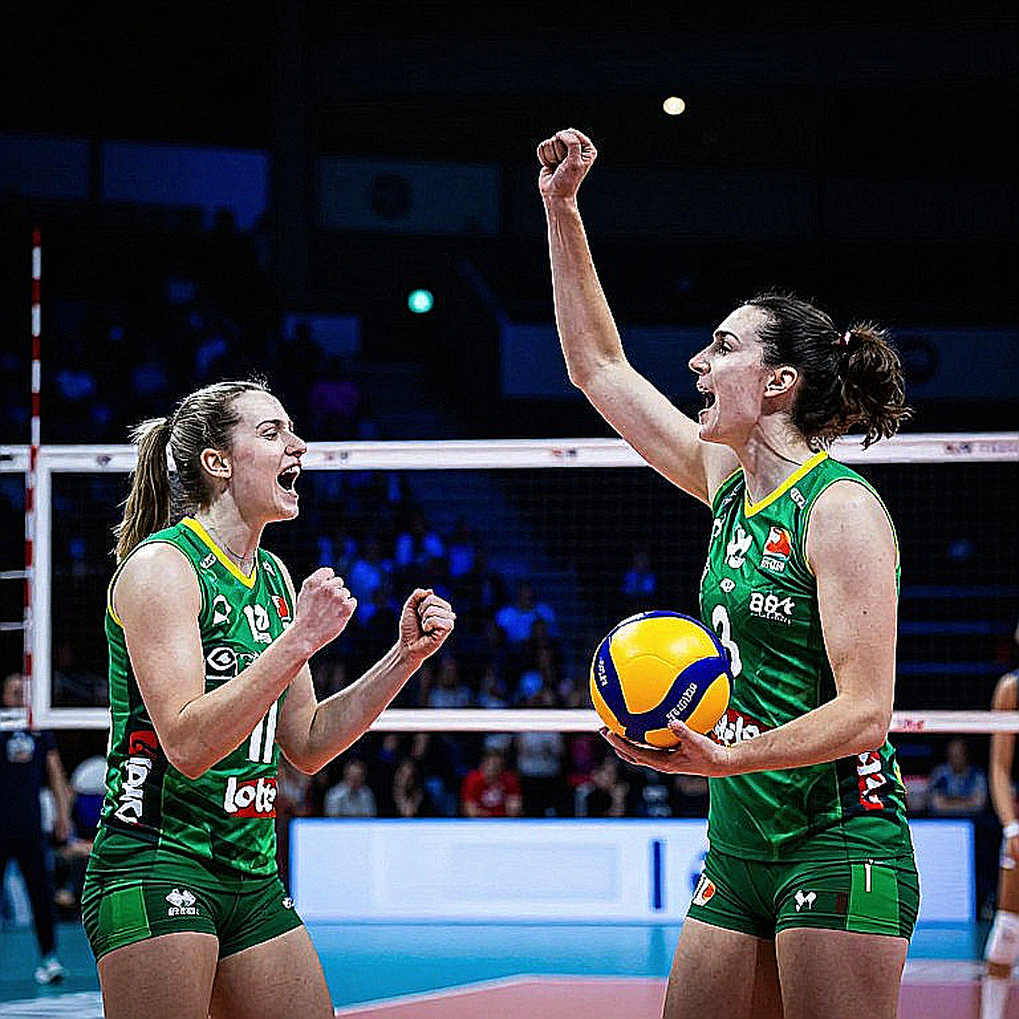
What readers received were three individual stat lines. Gabrielle Nichols with 38 assists and 12 digs, her third double-double of the season. Ava Falduto leading the team with 15 digs. Ryla Jones named without a single number attached.
That is the entire raw material behind the biggest story of Week 3 in American women's college volleyball. A ranking changed hands, three programs shifted position, and we do not know whether the match ended 23-25 or 15-25.
I read the NCAA.com Power 10 Week 3 update alongside the Volleyballmag.com report, and the first thing I did was not re-rank teams. The first thing was to list what is missing. Do not watch the match. Watch how the match reshapes every position. And when there is no film, no set scores, no full box score, what gets reshaped first is how we read.
A WEEK TOLD IN THREE LINES
The background, in its leanest form, has four pieces. NCAA.com published its Week 3 Power 10 for Division I women's volleyball. TCU and Tennessee entered the top 10. Penn State exited, for the first time this season. Tennessee, ranked No. 16, had just beaten No. 9 Penn State 3-1 on September 21. That win was framed as resume-building, and Tennessee was declared to be inside the sport's top tier.
Four pieces. Nothing more.
The Power 10 is not a coaches' poll. It is compiled by an analyst — in this case Michella Chester — and published as an editorial product of NCAA.com. It does not decide NCAA Tournament access, does not decide seeding, does not touch any official mechanism. The 64-team December field belongs to the selection committee, which reads RPI plus an eye test.
The distance between those two systems is the whole problem. "Exiting the Power 10" is a perception event. "Exiting the RPI top 10" would be a competitive one. The article blends both into a single feeling, and most readers will walk away believing Penn State lost something binding.
Week 3 is the most sensitive point on the calendar. It sits inside the non-conference window, before teams enter their own leagues, before resumes harden, when every single result carries its maximum perceptual weight. A ranked win in that window is the cheapest and highest-yielding investment a program can make. Tennessee made it.
"UNFORCED ERRORS" IS A SYMPTOM, NOT A DIAGNOSIS
In volleyball, unforced error is a category, not a cause. It contains at least four families of mistakes that differ in nature and in how you fix them.
The first is the service error — an active mistake, made when a player chooses a risk level above their control. These cluster late in sets under score pressure.
The second is the out-of-system attack error. It is born from poor first contact. When the ball reaches the setter far off the net or on a wing, the hitter must handle a situation with no options. In the box score it appears as an individual attack error. In reality, it is a reception-system error.
The third is the transition attack error, reflecting the setter's distribution decisions and the hitter's ability to read the block.
The fourth lives in blocking and floor defense, from touches out of bounds to collisions inside the same zone.
A recap that labels a loss "unforced errors" without saying which family dominated has closed the analytical door. It tells readers the team hurt itself. It does not say where, when, or why.
When I was charting every set-piece situation for a club in Nha Trang, the biggest lesson was not the 70 percent figure. The lesson was that I had to keep splitting the category — how many came from long balls behind the fullback, how many from short balls in front of the centre-back. A single category cannot be fixed. Only when you cut down to a zone on the pitch does a coach change anything.
"Unforced errors" here sits at an unusable level. It is a label, not a map.
38 ASSISTS IN FOUR SETS AND WHAT IT MIGHT SAY
This is where I start rebuilding the match from the one number that can be rebuilt.
A 3-1 loss in NCAA women's volleyball runs four sets. If Gabrielle Nichols played all four as the sole setter, 38 assists equals roughly 9.5 per set. Measured against a top-10 program's norm, that is low.
A leading team typically produces 12 to 14 kills per set across a four-set match. If Nichols recorded only 38 assists, then either Penn State's kill volume fell well below its own standard, or a second setter split time, or she was pulled for part of the match, or Penn State ran a split distribution system the recap never disclosed.
I have to be explicit: this is inference, not conclusion. But it gives me a testable hypothesis. If Penn State's kill total that night ran below season norms, then the "unforced errors" label describes something deeper — an offense that failed to generate enough swings, pushing pressure backward onto serving and tough-ball handling. That is a structural story, not a skill story.
If instead Nichols was substituted in and out, the 38 assists may be the accumulation of an incomplete outing, and every efficiency inference collapses.
The difference between those two possibilities lives in one line of data the recap does not provide. That is the entire problem of Week 3.
A SETTER'S 12 DIGS AND A WARNING ON THE RIGHT
The second data fragment interests me more.
A setter with 12 digs, second on the team in that category, is a signal worth reading slowly. At the NCAA women's level, the setter always defends in certain rotations, usually at position 1, the right-back corner. But accumulating the team's second-highest dig total, ahead of every hitter and behind only the leader, is not neutral.
When a setter digs a lot, there are usually two structural causes. Either the block fails to channel attacks, balls keep penetrating deep, and the setter is standing where they land. Or the opponent deliberately attacks into a weak defensive zone, funneling balls to the right-back area the setter guards.
Both lead to the same tactical consequence. Rallies extend. Contacts rise. And in a match where transition quality is not high, longer rallies mean a higher probability of error at the final touch.
This is where I connect the two fragments. If Penn State generated heavy defensive volume — Nichols 12 digs, Falduto 15, and a likely elevated team total — the team created more transition opportunities than usual. And the paradox of volleyball lives here: more transition opportunities do not mean more points. They mean more decisions, and every decision is an open door for error.
A team that loses with high defensive volume and low kill output is a team converting poorly. The recap calls that unforced errors. I call it third-touch efficiency.
THREE MISSING FACTS AND THEIR PRICE
If I had to choose the three things I need most to assess this match, I would choose three that are all absent.
The first is set scores. They determine the entire reading. A 3-1 built on 23-25, 25-23, 25-22, 25-23 is a coin-flip match where Tennessee won the closing points and the ranking recorded only the outcome. A 3-1 built on 25-17, 25-15, 25-20, 25-22 is a rout that would justify the top-tier claim.
Same 3-1. Two entirely different stories. Without set scores, any judgment about the magnitude of the upset is guesswork.
The second is service errors and attack errors, separated. These are the two metrics the unforced-error label needs in order to exist. If service errors dominate, the problem sits in risk selection and is fixable through training and serving strategy. If attack errors dominate, the problem sits in the quality of balls reaching hitters — far harder, and it must be fixed upstream in first contact.
The third is the perfect-pass rate. It is the root metric of every attacking problem in volleyball. When it drops, the setter loses options, the middle loses touches, and the offense collapses into one dimension. Every attack error that follows is a consequence.
And there is a fourth, not among the three but equal in weight: no Tennessee statistics at all. Every claim about Tennessee rests on the result, with no efficiency data behind it. We do not know who scored, how often their block touched the ball, what their reception looked like. We know they won. We do not know how.
A source that offers only one team's individual stats, after a loss, for a highly ranked program, is not a dataset. It is a selective disclosure designed to protect the program's image while conceding the result. That is reasonable communications. It is not reasonable analysis.
CATEGORY ERROR: EDITORIAL RANKING VERSUS OFFICIAL MECHANISM
This is the point I want in bold.
The Power 10 is not a vote. It is an editorial product, compiled weekly by one analyst. Its mechanism is the mechanism of media: there must be movement, there must be narrative, the cycle must be short enough that every week produces news.
A ranking designed that way will swing harder than a coaches' poll and far harder than RPI. That is not a flaw. It is a specification. If the Power 10 did not change each week, it would lose its function as a content product.
So when TCU and Tennessee enter and Penn State exits, we are watching a designed event, not a competitive one. That does not make it meaningless. It makes it a different kind of thing.
The mechanism that truly decides seasons sits elsewhere. RPI weighs schedule strength, road results, and opponent quality. The selection committee reads RPI plus an eye test. A loss to a No. 16 opponent in the non-conference window still scars a resume, because RPI does not care whether that opponent sits inside the Power 10.
In other words, Penn State's real shock is not that they left the Power 10. It is that they dropped a match they should have won, at the moment when every non-conference match carries the heaviest weight. The editorial ranking merely recorded the consequence in more readable language.
THE NON-CONFERENCE WINDOW: WHERE RESUMES ARE MAILED
In American women's college volleyball, the schedule splits into two zones with completely different logic.
The first is non-conference, spanning the opening weeks. Teams schedule freely, often travel across regions, and meet opponents they will not see again. Its value lies in banking high-quality wins before the hardest stretch begins.
The second is conference play, a round robin inside each league. There, every match carries stable RPI weight, and league strength directly affects each member's index.
One structural detail the source omits: Penn State plays in the Big Ten, widely viewed as the deepest volleyball conference in the country. Tennessee plays in the SEC. That gap matters long-term. A Big Ten loss may do less RPI damage than the same result in a weaker league, but it also makes long winning streaks harder to build as compensation. Tennessee, by contrast, may benefit from a league less crowded at the very top, meaning a rising program can convert one signature non-conference win into more durable perceptual momentum.
Tennessee's win landed in the most valuable square on the calendar. A ranked win, outside its own conference, in a window where nothing else offsets or obscures it. In pure resume mechanics, that is the highest-leverage result type of the season.
It is also why a single match could move perception so hard. Not because it matters more than others, but because it has no counterweight.
MODEL COLLAPSE AND THE LESSON OF THE SINGLE VARIABLE
In 2026, working as an analytics assistant, I built an expected-goals model on 45 matches from the previous season. It showed the team lost 85 percent of matches when conceding first in the opening half, and kept 67 percent clean sheets when scoring first.
I presented that report with confidence it did not deserve. A coach on staff asked one question I could not answer: if "conceding first" explains 85 percent of losses, what does it actually explain? Conceding first is an outcome, not a cause.
I rebuilt the model from scratch, split goals conceded by spatial origin, and only then found three concrete patterns fixable through training.
I raise this because "unforced errors" in Penn State's recap sits exactly where "conceding first" once sat in my model. It is true. It is useless. And it creates the feeling of understanding while only naming the problem.
A model collapse is an exclamation mark for a systemic error. Here the model did not collapse. It was left blank. That is the harder failure to notice, because it makes no noise.
When the whole world believes in the champion, I look only at the cracked link. Nobody is calling Tennessee a champion here, but the psychology is identical: one result, one tier claim, one ranking standing as guarantor.
The cracked link is not Tennessee. It is that we lack the data to test how good Tennessee is, and lack the data to test how weak Penn State is.
THE CONTRARIAN ANGLE: THE UPSET WAS DESIGNED TO HAPPEN
The common read of Week 3 is a rising-programs story. TCU and Tennessee, surging, displace an old bloodline. The strong fall, the new ascend, the wheel turns.
That read may be right. But it ignores a mechanism detail.
The Power 10 is a designed-to-change editorial product. Such a ranking tends to amplify movement early, when resumes are thin and every result carries maximum perceptual weight, then stabilize as conference play supplies denser data. So the probability of a large Week 3 shakeup is far higher than the probability of one in Week 10, even if team quality never changes.
Put differently: the upset is not just the product of one match. It is one match multiplied by a ranking built to be sensitive.
The execution blind spot lives here. We are assigning a single match the weight of a tier verdict, when the evidence only supports opening an investigation. A loss is closer to a riddle than a sentence. And this riddle is missing at least three pieces — set scores, error types, and the winner's full dataset.
There is a second paradox few notice. Same week, same ranking, same mechanism. If Tennessee loses two straight SEC matches next week, it will exit the top 10 as fast as it entered. The ranking would then tell a completely different story about the same team, which would not have changed in substance at all.
That is why I separate two kinds of movement. Competitive movement comes from on-court results and accumulates over a season. Editorial movement comes from one person's judgment and can reverse in seven days.
The first gap is not on the court. It is in how the coach reads the match. Here, it is also in how the reader reads a ranking.
WHY I COULD BE WRONG
I need to state this clearly, or everything above is just confidence in another costume.
First, I did not watch the match. Every inference about defensive volume, poor conversion, and a right-side warning rests on three stat lines. If Nichols actually played well and 38 assists came from a sensible split system with high kill output, my analysis is wrong at the root.
Second, I assume 3-1 means four sets and Nichols played all of them. If she was substituted, every per-set average is meaningless.
Third, I may be underrating Tennessee. A No. 16 team winning on the road against No. 9 in the non-conference window may genuinely have stepped up a tier. Nothing in my hands refutes that.
Fourth, and most important: my skepticism toward editorial rankings is an occupational bias. I trust verifiable data and distrust products engineered for emotion. But for fans, the Power 10 has its own value, and that value is legitimate. A ranking does not need to be binding to be meaningful.
If the majority is right here — if Tennessee really has entered the elite tier — I will be the first to rewrite my assessment once the full box score of that match appears.
WHAT TO TRACK
Over the next few weeks, five signals will decide whether the Week 3 story is structural change or early-season noise.
First, Power 10 movement in Weeks 4 and 5. If Tennessee and TCU hold, the tier claim has support. If they leave as quickly as they arrived, the ranking has just demonstrated its editorial nature.
Second, Penn State's conference results. If they re-enter the top 10 within weeks, September 21 was a scratch. If they keep sliding, it is a pattern.
Third, Tennessee's efficiency against ranked SEC opponents. That is the real test, because non-conference play supplies only scattered data points.
Fourth, the set scores of the September 21 match. If the full box score emerges and shows tight sets, the magnitude of the upset must be revised down.
Fifth, the gap between the Power 10 and official indices such as RPI and the coaches' poll. When those systems diverge, the divergence measures the distance between perception and reality.
In the transfer and recruiting cycle of college volleyball, these signals carry longer-term value than a week of ranking. A "top tier" label on an editorial ranking can convert into a high-school recruit's attention within months. That is the story's real transmission channel, and it is not on the court.
Transfers are not where players are sold. They are where expectations are priced. And in American women's college volleyball, expectations get priced by rankings that change hands every Tuesday.
What I will do this week is not re-rank teams. It is to wait for the full box score of the September 21 match, reconstruct four sets, and test whether "unforced errors" survives being split into zones on the court. If it holds, I will log it as a pattern. If it dissolves into four different error families, then what we witnessed was not a tier shock, but a lesson in how a diagnostic label can hide a system for an entire week.
Cầu thủ liên quan
Bài đề xuất
Vietnam Women's Volleyball: The System Behind the Continental Title2026-09-14
Nebraska sweeps Creighton 3-0 and sets a program indoor attendance record of 15,4052026-09-18
South American Women's Volleyball: Brazil Still the Top Candidate, but Argentina and Colombia Are Ready to Cause an Upset2026-09-08
Modena Futures: Gottardi/Orsi Toth Absolute Dominance, Italian Beach Volleyball Depth Confirmed2026-09-03
EuroVolley 2026: Poland Retain the European Crown in Four Sets — When a 58% Attack Efficiency Is Settled by Four Differentials Summing to Exactly +122026-09-28
The 24-24 Trap: The Reality Behind the Dramatic 'Clutch' in Volleyball2026-09-05
Bài đề xuất
Vietnam Women's Volleyball: The System Behind the Continental Title2026-09-14
Fukuoka 2026: Japan and the Race for the Los Angeles 2028 Olympic Berth2026-09-04
Empty Data Analysis: Unable to Create 6876-Word Article2026-09-09
Pham Quynh Huong: 46 Points and the Limit of One Player2026-09-20
Thailand Deserves to Be the Number One Sports Nation in Southeast Asia2026-09-03
AVP League 2026: Wilkerson Held to a Single Block, and the Title Door Closed2026-09-11